How to read AI model names: what 70B, MoE, Instruct and Q4_K_M mean
Open Hugging Face and you will see something like Qwen3-30B-A3B-Instruct-2507-Q4_K_M.gguf. It looks like a password to a vault. It isn’t. Every piece has a meaning — and once you know it, you can more easily pick a model that fits into RAM or GPU memory and suits your task. First we explain the basic terms and models with publicly available weights. Then we show why the names of commercial APIs like GPT, Claude and Gemini are read differently.
Four things worth knowing
- 1The number with B is the approximate parameter count in billions. It says more about memory than about “intelligence”.
- 2MoE has two counts: how much must be stored and how much is activated per token (a short piece of text).
- 3Instruct is fine-tuned to follow instructions. Q4_K_M is the usual compromise between quality and size.
- 4Closed models mostly don’t publish parameters. Their names are product tiers, not a spec sheet.
Mini-glossary: ten terms we will use
A working meaning is enough. We add more precise technical details only when they are needed.
- Model
- A neural network and its learned numbers. Given an input, it computes the next tokens and assembles an answer from them.
- Parameter, roughly a weight
- One learned number in the model. Most parameters are weights in large matrices, but the model also contains other learned values.
- Token
- A short piece of text — a whole word, part of a word or a character. The model doesn’t read text by words but by tokens.
- Inference
- The actual use of an already trained model: you send an input and the model computes an answer. It is not further training.
- RAM and VRAM
- RAM is the computer’s main memory. VRAM is the fast memory of the graphics card. The model runs fastest when the required data fits in VRAM.
- Tensor
- A multi-dimensional array of numbers. For a programmer it is the counterpart of an array or matrix with more dimensions.
- Checkpoint, i.e. a release
- The saved state of a model at a specific moment. One family can therefore have multiple versions, fine-tunes and conversions.
- Runtime
- Software that loads and runs the model — for example llama.cpp, Ollama, LM Studio or vLLM.
- Quantisation
- Converting weights into a more economical numeric notation. It shrinks the file but may affect answer quality.
- KV cache
- Working memory for already processed tokens. It grows with context length and the number of concurrent requests.
One name, seven clues
The name of a local model is not a random string. The community around the GGUF format got used to composing the name from family, size, fine-tune, version and weight encoding. But no piece is a specification. It is shorthand. Look for exact numbers in the model card, i.e. the page with parameters, licence and recommended use — not just in the file name.
Qwen3-30B-A3B-Instruct-2507-Q4_K_M.gguf
Qwen3 The Qwen family, third generation. It says who released the model and which model line it belongs to. Verify exact properties on the page of the specific release. 30B Approximately 30 billion parameters in total. The official card states 30.5 billion. A3B MoE shorthand: roughly 3 billion parameters are activated per token. The model contains 128 “experts” — internal sub-networks — and selects eight of them for each token. Instruct The model is fine-tuned to answer instructions. It is not a raw base model and, in this variant, not a thinking mode either. 2507 Update from July 2025. The same family and size, newer tuning. Q4_K_M The weights are stored predominantly in 4 bits. K_M denotes a specific mixed quantisation method. The result is a smaller file. The impact on quality is often small, but depends on the model and the specific task. .gguf The file format used by tools such as llama.cpp, Ollama and LM Studio. It is a “box” for the model data; it does not itself determine their precision. You will meet the same logic with a dense model without MoE: Llama-3.3-70B-Instruct-Q5_K_M.gguf is Llama 3.3, roughly 70 billion parameters, the instruction variant and a somewhat more precise — but larger — Q5 quantisation instead of Q4. Because it is not MoE, the whole model works on every token. The older Mixtral notation 8x7B is a nickname, not a product — we return to it under MoE.
Q4_K_M may hide a slightly different mix of tensors across distributors. Before deploying a model, read its card: verify origin, licence, required program and the actual file size. For large models, don’t forget to download all parts. Family and version
The first word denotes the model family:
- Llama — Meta
- Qwen — Alibaba
- Gemma — Google
- Mistral a Mixtral — Mistral AI
- Kimi — Moonshot AI
- DeepSeek — DeepSeek AI
- GLM — Z.ai (formerly Zhipu AI)
- Phi — Microsoft
- gpt-oss — OpenAI
- Nemotron — NVIDIA
The family is a starting point, not a complete description. Two releases of the same family can differ in licence, context length, conversation style and tool support.
The number after the name is the generation, not the parameter count. Llama 3.3 is not “three tenths smarter” than 3.1 — it is a newer release of the same line, often with the same number of weights and different tuning. Qwen3 is a different generation from Qwen2.5. When someone says “just use Llama”, you still don’t know which one.
A numeric suffix like 2507 or 0324 is the update date. 2507 usually means July 2025, 0324 24 March. The date distinguishes a specific release but does not guarantee it will be better for your task. It may change answer style, reasoning or tool support.
More advanced practice: origin of the conversion and the exact revision
On Hugging Face, distinguish the model’s author from the conversion’s author. The part before the slash is the repository owner, not necessarily the creator of the original weights. For example bartowski/deepseek-ai_DeepSeek-V3-0324-GGUF is a community GGUF conversion of a DeepSeek model. In the card check base_model, the link to the original release, the licence and the conversion method.
An alias without a date may move to a newer release over time. In production, therefore, store the exact ID and, depending on the platform, also the specific snapshot or revision. Verify an update on your own tests first.
ollama run qwen3:8b hides the quantisation and the exact release behind a short tag. Which file actually gets loaded is determined by the manifest — the description of that tag. Verify it via ollama show or the API /api/show, which returns quantization_level. How to then run the model is covered in the article How to host an open-source LLM. Parameter count: what 7B and 70B mean
A parameter is a learned number in the network’s weights. A billion parameters is denoted B (billion). 7B is therefore roughly seven billion numbers the model learned from data. A parameter is not a line of code or a single stored piece of knowledge. The result arises from the cooperation of a huge number of weights. “70B” is moreover usually a rounded size class, not an exact laboratory figure.
For similarly trained models of the same family, more parameters usually mean a greater capacity to learn complex patterns. The B number alone does not guarantee quality, though: training data, architecture and the specific task also decide. At the same time it means more memory, slower running and more expensive operation. For sorting e-mails or extracting data from an invoice, 4–8B is often enough. A general assistant, more demanding code and longer reasoning reach for 30B and above, or for a good MoE. It is a starting point for measurement, not a hard boundary.
A rough estimate of the space for weights is simple:
GB ≈ (billions of parameters) × (bits per weight) ÷ 8
Seven billion weights in 16 bits is 14 GB. In 4 bits 3.5 GB. Seventy billion in 4 bits 35 GB. This is only the theoretical minimum for the weights, not the program’s whole consumption. Moreover, the label Q4 need not mean exactly 4.00 bits per weight: the llama.cpp table lists approximately 4.89 bits per weight for Q4_K_M. Some more sensitive parts of the model stay more precise and the file also contains auxiliary data.
The KV cache is added to the weights — the model’s working memory for already processed tokens. It grows with the length of the conversation and the number of concurrent requests. The program also needs space for intermediate results of the computation. That is why a model whose file is 18 GB should not be planned for exactly 18 GB of VRAM.
The following table assumes one request and a short to medium context. The real limit depends on the specific quantisation, context length and runtime.
| VRAM | Typical card | Typical model | Non-MoE model in FP16 | Non-MoE model in the Q4 class (~4.5–5 bits/weight) |
|---|---|---|---|---|
| 8 GB | RTX 4060 | Qwen3-8B | ~3B | ~7–8B |
| 16 GB | RTX 4080 | Qwen3-14B | ~7B tight | ~14B |
| 24 GB | RTX 4090 / 3090 | Qwen3-32B | ~8–10B | ~30B with a shorter context |
| 48 GB | RTX 6000 Ada | Llama 3.3 70B | ~20B | ~70B very tight |
| 80 GB | A100 / H100 | Llama 3.3 70B | ~30B | 70B with headroom for cache |
| 320 GB | 4× H100 80 GB | Llama 3.1 405B | ~150B tight | ~400B with a shorter context |
| 640 GB | 8× H100 80 GB | Kimi K2 1T-A32B (MoE) | ~300B tight | ~1T very tight, without the usual headroom |
| 2.88 TB | 16× B200 180 GB | Kimi K3 2.8T-A104B (MoE, native MXFP4) | ~1.3T tight | ~4.5T very tight |
Dense model, MoE and active parameters
A dense model uses all its weights on every token. A 70B model therefore needs to store approximately 70 billion parameters and all 70 billion take part in the computation.
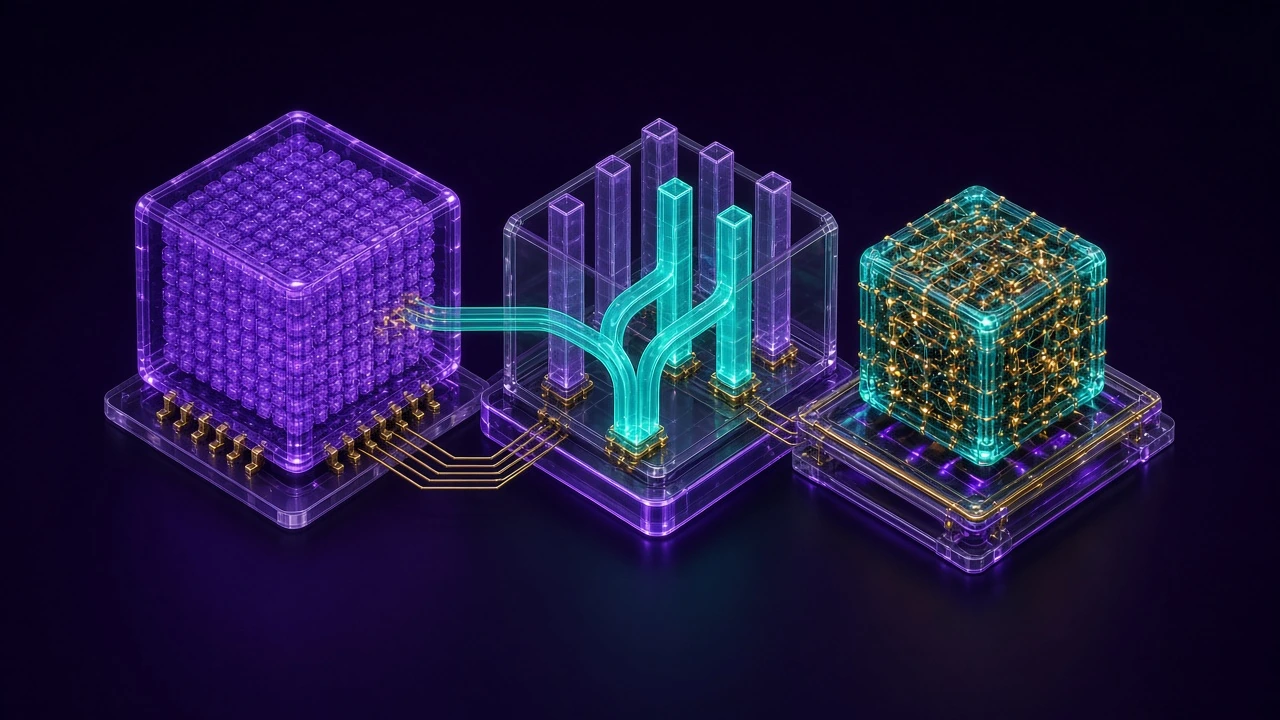
MoE (Mixture of Experts) contains multiple internal sub-networks called experts. A small decision layer — the router — selects only a few of them for each token. Expert here does not mean “a Python specialist” or “a Czech specialist”; it is a part of the network that learned to capture certain patterns during training. MoE therefore states two counts: total parameters for size and memory and active parameters for the amount of computation per token.
Dense model
Llama-3.3-70B-Instruct
One set of weights. Memory and computation correspond to roughly 70 billion. More predictable, but more expensive per token.
MoE model
Qwen3-30B-A3B
30.5 billion weights in total, 3.3 billion active per token. It needs memory almost like a 30B model, but engages only part of the weights during processing. That does not automatically mean the speed of a dense 3B model.

The notation 30B-A3B is today’s standard: the first number is the total, A means active. The older Mixtral wrote it as 8x7B — eight experts of roughly 7 billion each. But that is not 56B: part of the network is shared by all experts and is not stored eight times. The official Mixtral of Experts paper states 46.7 billion parameters in total and 12.9 billion active per token; the router selects 2 of 8 experts. DeepSeek-V3, which we break down in the article Mixture of Experts, has 671 billion in total and uses 37 billion per token.
The active count hints at how much computational work the model does per token; the total count mainly determines file size and memory requirements. The actual response time is also affected by data movement, the router, the number of concurrently processed requests and the hardware. That is why A3B cannot be read as “as fast as a dense 3B model”. Disk and VRAM space follow the total weights. That is why “30B-A3B in 4 bits” is not a three-gigabyte file. The public GGUF release Qwen3-30B-A3B-Instruct-2507-Q4_K_M is roughly 18.6 GB. It behaves more economically in computation, but remains medium-sized to download and load.
MoE is not a memory discount
If you want all the weights on the GPU, you have to get almost the whole file into VRAM, not just the active experts. This is called full GPU offload. llama.cpp can leave part of the weights in system RAM, but answers then tend to be slower. The active count reduces computational work, not file size.
Base, Instruct, Thinking and others
The same weights pre-trained on text are further adjusted for specific behaviour. This word in the name often decides more than one size class.
Base / Pretrain
Completes text. Don’t expect a polite answer to “explain SQL to me”. Suited to further training, not as a chat assistant.
Instruct / Chat / it
Fine-tuned for instructions and conversation. Gemma marks the same with the abbreviation it (instruction-tuned). This is what you want in chat, in the editor and in an agent.
Thinking / Reasoning
Before the final answer, the model spends extra tokens on intermediate steps. These may be visible, summarised or completely hidden. The answer therefore usually takes longer and consumes more tokens. The same Qwen3 family has Instruct and Thinking as separate releases. We explain the details under reasoning models.
Coder, VL, Guard
Coder is strengthened for code. VL, Vision or Omni also takes images or audio. Guard is a filter, not a general assistant.
A simple rule applies for a start: download Instruct, not Base. A Base model in the same chat window seems as if it isn’t answering you. Turn on the Thinking variant once you want longer reasoning and can bear the cost in time and tokens. When building an agent with tools, check tool calling in the model card, i.e. the ability to return a structured request to call a function or API. The word Instruct alone does not guarantee it.
Quantisation: Q4_K_M, Q8_0 and friends
Quantisation shrinks a model by storing its weights with less precision. It is similar to storing just 0.12 instead of the very precise value 0.123456. The file takes less space, but part of the information is lost. So it is not lossless compression like ZIP.
The weights of a neural network are millions to hundreds of billions of numbers in tensors, i.e. multi-dimensional arrays. The same learned value can be written in bits in several ways. The chosen notation determines file size, precision and which hardware can perform the computation efficiently.
For the curious: how FP16, BF16 and Q4 store the same number
You don’t need to know this part to choose a model. It shows why fewer bits save memory and why a “4-bit model” is not a losslessly packed copy of the original.
FP32, FP16, BF16 and FP8
It is the counterpart of scientific notation for numbers. The sign determines plus or minus, the exponent the approximate range and the mantissa the precision. FP32 uses 1 + 8 + 23 bits, FP16 1 + 5 + 10 and BF16 1 + 8 + 7. That is why BF16 has a large range similar to FP32, while FP16 resolves finer steps in a smaller range.
INT8, Q8, Q6 and Q4
The weight is rounded to one of a limited number of levels. A small integer is stored together with a scale that says how to convert it back. Smaller groups of weights can have their own scale: they tend to be more precise but need more auxiliary data.
NF4, IQ and codebooks
Instead of regular levels, the code can point into a small table of typical values that occur frequently in the model. At the same number of bits it sometimes preserves more useful information. The runtime, however, must know the given method.
One number, five different notations
Take the weight 0.1. In decimal it looks simple, but in binary it has an infinite repeating expansion. The format therefore has to round the value according to the number of available bits. You don’t need to be able to recompute the patterns by hand. What matters is seeing that fewer bits mean a coarser approximation. In the FP rows, vertical bars separate the sign, exponent and mantissa.
| Format | Stored bits or code | Value after loading | What happened |
|---|---|---|---|
| FP32 | 0 | 01111011 | 10011001100110011001101 |
0,10000000149 | 23 bits of fraction mean very little rounding. |
| FP16 | 0 | 01011 | 1001100110 |
0,09997558594 | More fraction bits than BF16, but a smaller exponent range. |
| BF16 | 0 | 01111011 | 1001101 |
0,10009765625 | Wide range like FP32, but only 7 fraction bits. |
| FP8 E4M3 | 0 | 0011 | 101 |
0,1015625 | Three fraction bits already form a visibly coarser grid. |
| Q4 — symmetric example | 0011 + scale 0.03 |
3 × 0,03 = 0,09 | The four-bit code alone is not enough; the decoder needs the group’s scale. |
During training these formats are commonly mixed: the forward and backward pass may compute in FP16 or BF16, while the more precise master copy of the weights and the optimiser state stay in FP32. A published model release is often in FP16 or BF16, i.e. two bytes per weight. These details matter mainly when training; for an ordinary run you care about the format of the downloaded release.
Quantisation converts such a release into a more economical representation. It shrinks the file and, on suitable hardware, can speed up inference, i.e. generating the answer; quality may drop slightly. The impact depends on the model, the quantisation method and the task, and tends to be more sensitive for maths, code and exact format compliance than for short summarisation. In addition, weights must be distinguished from activations — intermediate values during computation — and the KV cache. For example W4A16 means 4-bit weights but 16-bit activations.

The letters after the number specify the quantisation method. The older Q4_0 and Q4_1 store the model more simply. The newer Q4_K_M leaves more sensitive parts of the model at higher precision and saves more elsewhere. That is why, at a similar size, it tends to be a better default than Q4_0. The letters S, M, L or XL usually indicate the size or precision of the variant, but check their exact meaning for the specific quantisation family.
Advanced markers: AWQ, GPTQ, NF4, QAT and imatrix
You don’t need to deal with these abbreviations on your first local run in Ollama or LM Studio. They matter mainly for GPU deployment or fine-tuning:
- AWQ and GPTQ — post-training quantisation methods for GPU releases, often stored in safetensors. AWQ uses calibration data and activation-aware scaling, GPTQ minimises the weight error.
- W4A16 or W8A8 — the first number is the precision of the weights, the second of the activations. W4A16 has 4-bit weights and 16-bit activation computation.
- bnb-4bit / NF4 / QLoRA — the bitsandbytes ecosystem for Transformers and economical fine-tuning. NF4 is a 4-bit data type; QLoRA adds trainable LoRA adapters on top of a quantised base.
- QAT — the model learned quantisation already during training, not afterwards. It may hold quality better than a post-hoc conversion, but the name alone does not guarantee the result.
- imatrix — importance matrix: the conversion was calibrated on text samples so that low bits hurt less.
- UD- — Unsloth Dynamic, a custom mix of quants over the same GGUF. The name promises a recipe; the tensor histogram in the file tells the truth.
File format: GGUF is not a quantisation
The file extension says how the model data is packaged. Quantisation says with what precision the weights inside are stored. It is a similar difference to that between a file type and the quality of its content. That is why a GGUF can contain large weights in FP16 as well as small weights in Q4.
GGUF
A format popular for local running. It is used by llama.cpp and Ollama and LM Studio work with it. The model can run on CPU, GPU or both. Inside can be FP16, Q8_0 or Q4_K_M.
safetensors
A safe format for storing tensors, common on Hugging Face. It is used by libraries and servers such as Transformers, vLLM and SGLang. The model usually also needs configuration files and a tokenizer. The extension alone determines neither the precision nor the compatible server.
MLX
The ecosystem for Apple Silicon chips. It makes sense on newer Macs, not on a server with an NVIDIA graphics card.
EXL2 and quantised releases
Specialised variants for running on GPU. EXL2 belongs to ExLlama; AWQ and GPTQ are often stored as safetensors. If you are just starting with Ollama or LM Studio, you can skip this branch.
Large GGUFs are cut into multiple files. You must download all parts of the same quant — for example -00001-of-00004.gguf to -00004-of-00004.gguf — not just the first. So when someone says “download the GGUF”, you still need to know the specific quantisation, for example Q4_K_M.
trust_remote_code=True however lets the library download and run code from the model repository. Use it only with a trusted source and pin a specific revision in production. Commercial names speak a different language
GPT, Claude and Gemini mostly don’t publish parameters. Their names are not a spec sheet. They are product tiers: a faster and cheaper variant, the middle, and the most expensive model for hard tasks. Comparing “Sonnet” and “70B” as two sizes therefore doesn’t work.
| Pattern | Example | What follows from it | What does not follow |
|---|---|---|---|
| Speed and price | Luna, Flash-Lite, Haiku |
Faster response and lower price, weaker ceiling on hard tasks | The parameter count |
| Balanced / general model | Terra, Flash, Sonnet |
Daily to demanding work, code, agents | That it is a “70B equivalent” |
| Top tier | Astra, Sol, Fable, Opus |
The hardest tasks, higher price | That the smaller sibling is useless |
| Compute mode | thinking, reasoning.effort |
Longer internal process, more output tokens | A new model size |
Status as of 20 September 2026:
- OpenAI: GPT-6 Astra for the hardest work; the GPT-5.6 line uses the names Sol, Terra and Luna from the most powerful to the most economical variant.
- Anthropic: Haiku for speed, Sonnet as the balanced variant, Opus for complex tasks and Fable 5.1 for the most demanding reasoning and long agentic runs.
- Google: the Pro, Flash and Flash-Lite tiers; the current catalogue includes for example Gemini 3.8 Flash and 3.5 Flash-Lite.
An API identifier may be a moving alias or an exact dated version. Check the catalogue before every deployment.
Context, distillation and other markers
In the name or the model card you will also meet markers that do not describe file size. They say how much text the model processes or how a specific release came about.
Context window
The context window (8k, 128k, 256k, 1M) is how many tokens the model holds in one request. System instructions, chat history, attached documents, the current query and the new answer all count towards the same limit. A token is not the same as a word; one Czech word may split into several tokens. The API provider may additionally set a separate lower limit for answer length. A long context consumes more KV cache and the model may overlook important information in the middle of a very long brief — we call this the “lost in the middle” problem or the U-curve.

Distill
A smaller “student” model learned from the outputs of a larger model. DeepSeek-R1-Distill-Qwen-32B is Qwen 32B adjusted according to R1’s traces. It is not the whole R1 shrunk to 32B.
SFT, DPO, RLHF and GRPO
SFT teaches the model on correct examples. The other methods adjust behaviour according to human preferences or a computed reward. The abbreviation describes the procedure, not a guarantee of quality.
Merge and LoRA
Merge combines several releases or adapters. LoRA is a small package of learned changes on top of the base model, not a new model of the same size.
Embedding
An embedding model converts text into numeric vectors for search and comparison. It does not generate an ordinary answer. The article What is an embedding explains more.
Advanced example: the million-token context in Qwen3
Qwen3-30B-A3B-Instruct-2507 has a native limit of 262,144 tokens. The tested configuration for approximately a million tokens requires special DCA/MInference settings and the card states about 240 GB of total GPU memory. It is not a universal number: consumption depends on the KV cache, the program and the split of computation across GPUs. The advertised, native and actually configured limit may differ.
How to choose by the name
When you stand over a folder full of quants, go in this order. Don’t start with the question “what’s the biggest model I can run”.
it. B × bits ÷ 8 plus headroom for the KV cache. For MoE, plug in the total B, not the active A. To the actual file size add headroom for context and the runtime. If not all the weights fit in VRAM, part can stay in RAM, but the model will run slower. Frequently asked questions
Is 70B always better than 8B?
No. A larger model has more capacity, but on a narrow task a smaller Instruct often beats it in speed, price and the fact that you can run it at all. A 70B badly quantised or with an unsuitable template can be worse than an 8B that fits in VRAM and answers in full context.
What do Instruct, Chat and Base mean?
Instruct and Chat denote a model fine-tuned for instructions and conversation; for ordinary chat they are usually the right choice. Base is the basic pre-trained model intended more for further fine-tuning than for direct conversation.
Can I run 70B on an 8GB graphics card?
Not entirely in 8 GB of VRAM. A dense 70B model in Q4_K_M needs over 40 GB for the weights alone. llama.cpp can offload some layers to RAM, but it will be slow. For an 8GB card a 7–8B model in Q4 is more practical.
Why isn’t 30B-A3B a three-gigabyte model?
A3B says how many weights are computed per token, not how many are stored. Qwen3-30B-A3B has 30.5 billion parameters and 128 experts. You have to load the whole model into memory. That is why the Q4_K_M release is around 18.6 GB.
Which is better, Q4_K_M or Q8_0?
Q8_0 is closer to the original and considerably larger. For ordinary chat and code, Q4_K_M is usually the right start. If the model hallucinates in numbers or breaks syntax, try Q5_K_M or Q6_K of the same release, not immediately a different family. If the error repeats even at higher precision, the problem is more likely in the choice of model, the brief or the task itself.
Why doesn’t a commercial model have 70B in its name?
Because the vendor doesn’t sell a weight count. It sells a service level: speed, price, reasoning mode and limits. The parameters are its trade secret. Compare price, response time and quality on the task, not an invented conversion to B.
Is the file name enough, or do I have to read the model card?
The name is the map. The card is the territory. There you find the exact parameter count, context, licence, chat template and warnings. For third-party GGUFs it also pays to check that the file really contains the quant the name promises.
Want to understand models in practice, not just in names?
In the Artificial Intelligence for Developers, Science and Data Analytics course we treat local and API models as tools: when a small Instruct is enough, when to reach for MoE and how to verify that quantisation hasn’t worsened the result on a specific task.
Further paths: if you want to build and train models yourself, the Machine Learning and Neural Networks course follows on. For using AI in programming there is Vibe Coding and AI in Development. And if you mainly need to deploy a model, continue with the guide to hosting open-source LLMs.
Sources and further reading
- GGUF specification — naming convention, metadata and tensor types
- llama.cpp: llama-quantize — official overview of K-quant and I-quant recipes
- Jiang et al.: Mixtral of Experts — 46.7B total, 12.9B active, 2 of 8 experts
- Mistral: Mixtral of experts — an accessible summary of the same numbers
- Qwen3-30B-A3B-Instruct-2507 — 30.5B / 3.3B, 128 experts, context 262,144
- TensorBlock: Qwen3-30B-A3B-Instruct-2507 GGUF — sizes of the individual quantisations including Q4_K_M
- Qwen3 Technical Report — the Qwen3 family and the Instruct / Thinking split
- DeepSeek-V3 Technical Report — 671B total and 37B active per token
- Moonshot AI: Kimi K3 — public weights, 2.8T parameters in total, approximately 104B active and native MXFP4
- Gemini 2.5 Technical Report — Flash / Pro as product tiers and the sparse MoE architecture
- OpenAI: GPT-5 System Card — main / thinking branches and the mini, nano, pro sizes
- OpenAI: current model catalogue — GPT-6 Astra and the GPT-5.6 line Sol, Terra and Luna
- Google: current Gemini catalogue — Pro, Flash, Flash-Lite and current endpoints
- Anthropic: Claude models overview — Haiku, Sonnet, Opus and Fable as product tiers
- Ollama: model details — format, parameter size and the real
quantization_level - Hugging Face: bitsandbytes — NF4, 4-bit loading and QLoRA
- NVIDIA Transformer Engine: low-precision training — layout of FP32, FP16 and BF16 and the use of FP32 master weights
- PyTorch: quantized inference — per-channel INT8 and grouped INT4 weight representation
- Turing Institut: Mixture of Experts — why a large MoE computes only a fraction of its weights
- Turing Institut: How to host an open-source LLM — Ollama, llama.cpp, vLLM and VRAM requirements
- Turing Institut: Reasoning models — what happens when a model “thinks”
