What is an embedding: how AI turns meaning into numbers
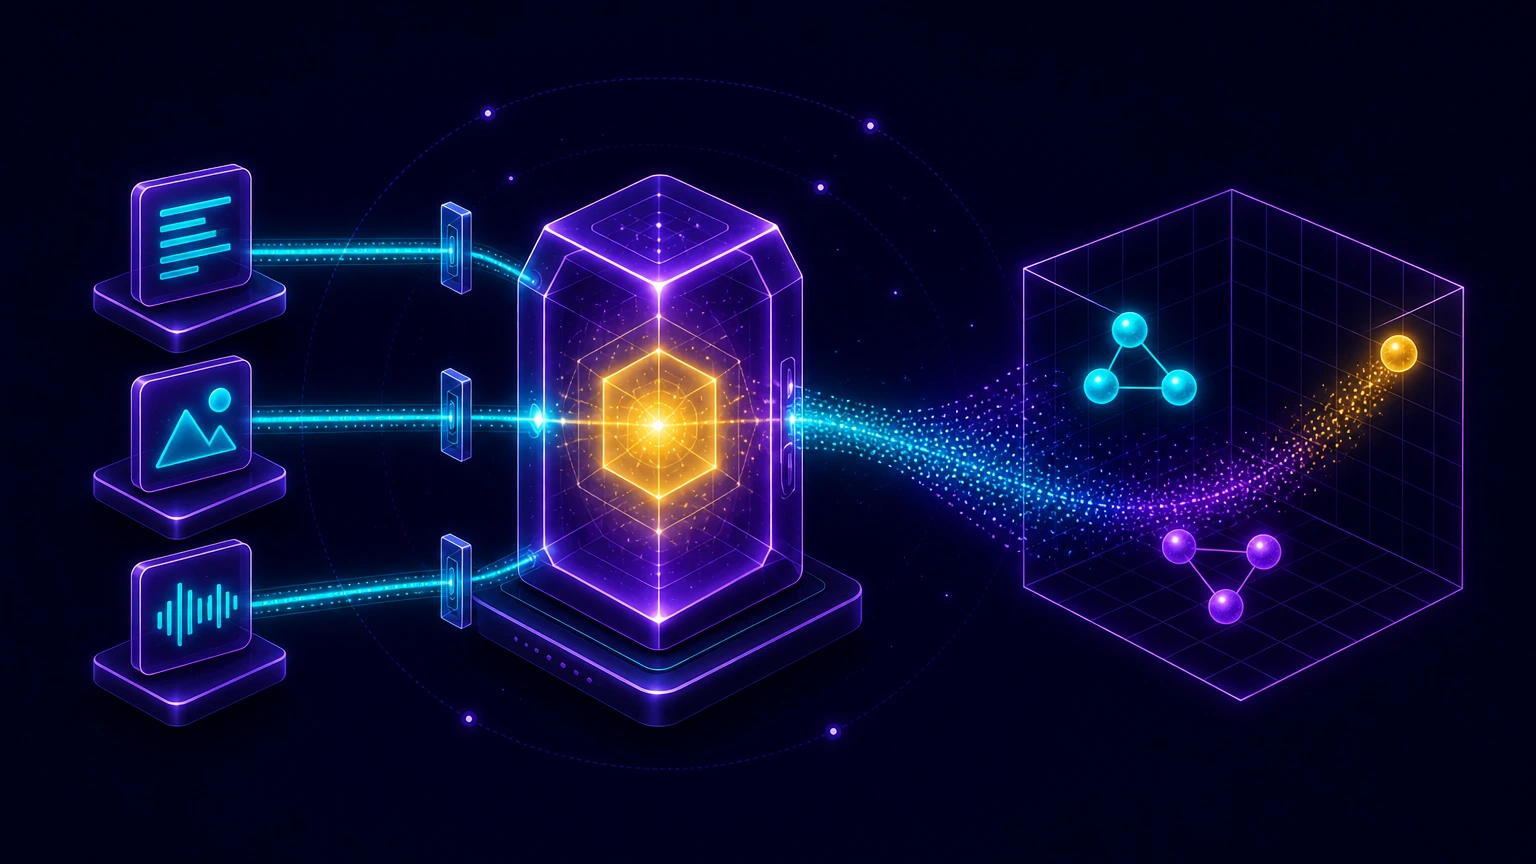
When you type “AI course for beginners” into a search, you also expect results titled “introduction to artificial intelligence”. The words don’t match, the meaning does. An embedding converts text, an image or another object into a numeric vector in which such semantic similarity can be computed.
What an embedding is
An embedding, also called a vector representation, is a mapping of an object into a space of numbers. The input can be a word, a sentence, a whole document, a photograph, audio, a product, a user or, say, a graph node. The output is an ordered list of numbers of fixed length:
The value 0.18 alone usually doesn’t mean “artificial intelligence” and −0.42 doesn’t mean “beginner”. The information is carried only by the whole vector and its position relative to other vectors produced by the same model.
The key property is: objects that the model, according to its training, considers similar end up close to each other. The embedding of the sentence “Python basics” may therefore be closer to “Python programming for beginners” than to “caring for fruit trees”. It is not, however, a general definition of meaning. It is a representation learned from the data and objective of a specific model.
Why AI needs vectors
A neural network doesn’t work directly with words or images. Its layers multiply matrices, add numbers and apply non-linear functions. The input must therefore take a numeric form. The simplest option for words is one-hot encoding: each word has a long vector full of zeros and a single one at its own position.
Such encoding distinguishes words but doesn’t capture their relationship. The vectors of the words “dog” and “puppy” are as far apart as “dog” and “database”. Moreover, they have as many dimensions as there are items in the vocabulary and most values are zero.
An embedding, by contrast, is a dense vector: it has considerably fewer dimensions and almost all values carry part of the information. The model learns its coordinates so that they are useful for the chosen task. For text this often means that expressions used in similar contexts get similar representations.
An embedding is not “understanding” in the human sense
A vector captures the statistical structure learned from data. That can be extremely useful for search and classification, but it doesn’t mean the model understands experience, intent or truth the way a human does.
How an embedding is created
The exact procedure depends on the architecture and training. For a modern text embedding model, four steps can be described in simplified form:
- Tokenisation. The text is split into tokens — whole words, parts of words, punctuation or other units. A Czech word can form one or several tokens.
- Initial representation. Each token gets an input vector from a learned embedding table. Information about order or position is added.
- Contextualisation. Transformer layers transform the representation of each token according to the surrounding text. The word “lock” can therefore have one contextual state in a sentence about doors and another in a sentence about a canal.
- Merging into a single vector. The model uses pooling or a special learned output to create a fixed-length vector from text of variable length. A model intended for similarity is trained specifically for this step.
The last point matters. Not every language model automatically produces a quality embedding of whole sentences. For example, simply averaging arbitrary hidden states of a Transformer need not give a space suitable for semantic comparison. The model should be trained or fine-tuned precisely for retrieval, similarity or another intended task.
What the model learns during training
The older word2vec learned to predict a word from its surrounding context, or conversely the context from a given word. Modern embedding models often use contrastive learning: they get pairs that belong together and hard negative examples that look similar but are not the correct answer. The goal is to bring relevant pairs closer and push irrelevant ones apart.
For search, a positive pair can be a question and the paragraph with the answer. A negative example is a paragraph on a similar topic that doesn’t answer the question, however. The choice of training pairs therefore directly affects what “close” will later mean.
The vector space as a map of meanings
Every embedding can be understood as a point in a multi-dimensional space. The two-dimensional map below is only an illustration: a real model may use hundreds or thousands of dimensions and part of the relationships is lost when projecting into two dimensions.
What the dimension of an embedding is
The dimension is the number of numbers in the vector. A vector of length 384 has 384 dimensions. More dimensions can give the model more capacity, but don’t automatically mean better results. They also increase storage size, the amount of transferred data and the cost of comparison.
A rough estimate for uncompressed float32 values is number of vectors × dimension × 4 bytes. A million vectors of 768 dimensions takes approximately 3.1 GB for the coordinates alone. Metadata, the database index, replication and operational overhead come on top.
How embedding similarity is measured
Once we have two vectors, we need a number expressing their closeness. Most often cosine similarity, the dot product or Euclidean distance is used. The right choice depends on how the model was trained and what its documentation recommends.
With cosine similarity, 1 is usually maximum agreement of direction, 0 orthogonality and −1 opposite direction. In practice, however, there is no universal threshold like “above 0.8 the text is relevant”. The distribution of scores depends on the model, language, data and type of query. The threshold must be derived from your own test set, or you work with the ranking of the best top-k results.
A simplified numeric example
Imagine only three dimensions. The query has the normalised vector q = [0.8, 0.6, 0]. Document A has a = [0.75, 0.66, 0] and document B b = [0.1, 0.2, 0.97]. The dot product of the query with A is considerably higher, so A ends up before B. A real model does the same kind of calculation in hundreds of dimensions; the numbers in the example are not the output of a specific model.
What types of embeddings exist
Symmetric and asymmetric search
In symmetric similarity we compare objects of the same type, for example two paraphrases. In asymmetric retrieval a short question is compared with a longer paragraph containing the answer. Some models require a different prefix or a separate encoding method for the query and the document. Ignoring this instruction can significantly reduce quality.
Practical example: semantic search in Python
The following small example uses a local multilingual model from Sentence Transformers. We normalise both documents and query, so matrix multiplication corresponds to cosine similarity. The model is suitable for an illustrative demo; for production, compare several models on your own data.
from sentence_transformers import SentenceTransformer
import numpy as np

model = SentenceTransformer(
    "sentence-transformers/paraphrase-multilingual-MiniLM-L12-v2"
)

dokumenty = [
    "Kurz vysvětluje základy Pythonu úplným začátečníkům.",
    "Neuronové sítě se učí z trénovacích dat.",
    "Fakturu pošleme po přijetí objednávky.",
    "Do umělé inteligence můžete vstoupit i bez předchozí praxe.",
]

vektory = model.encode(
    dokumenty,
    normalize_embeddings=True,
)

dotaz = "Jak začít s AI, když nemám zkušenosti?"
vektor_dotazu = model.encode(
    dotaz,
    normalize_embeddings=True,
)

skore = vektory @ vektor_dotazu
poradi = np.argsort(skore)[::-1]

for index in poradi[:3]:
    print(f"{skore[index]:.3f}  {dokumenty[index]}")
The output sorts the texts by similarity to the query. The exact scores may change with the version of the model and library. What matters is the order: the sentence about getting into AI should rank higher than the sentence about an invoice, even though the query doesn’t use the same wording.
For a few thousand items, similarity can be computed directly in NumPy. For millions of vectors, a specialised index for approximate nearest neighbour search is used.
From embedding to semantic search
A vector database stores the embedding together with the identifier of the original text and metadata, for example language, document type, date or user permission. For a query it returns the nearest vectors. The original content is usually loaded by the stored identifier.
For fast search in a large collection, Approximate Nearest Neighbor (ANN) indexes are used. A well-known example is HNSW, which organises vectors into a multi-layer graph. The search need not visit every point, but the price for speed is the possibility of missing some truly nearest neighbour. Index parameters therefore balance speed, memory and recall.
A more detailed look at storage, metadata and indexing is in the article What is a vector database and how AI agents use it.
When embeddings alone are not enough
Semantic search can overlook an exact product code, a contract number, an unusual abbreviation or a new proper name. Full-text search, by contrast, is strong in exact word matching. Production systems therefore often use hybrid search: they combine a lexical score, for example BM25, with vector similarity and re-rank the results.
The next step is a reranker. A cheap embedding index quickly selects, say, 50 candidates and a more accurate model that sees the query together with each candidate builds the final ranking from them. This separates fast candidate retrieval from the more expensive relevance assessment.
How embeddings work in RAG
RAG, or Retrieval-Augmented Generation, connects search with a generative model. In it, embeddings often handle the first part — retrieval:
- Documents are split into smaller excerpts, or chunks.
- Each chunk gets an embedding and is stored in the index.
- The user query is converted into a vector by the same model.
- The system finds relevant chunks, optionally filters and re-ranks them.
- The selected texts are inserted into the language model’s context.
- The model produces an answer and ideally cites sources.
So the embedding doesn’t generate the answer. It helps decide which material the generative model should receive. If retrieval selects the wrong documents, even a strong language model won’t produce a reliable answer from them.
Chunking: how much text to put into one vector
A whole long manual can technically be converted into a single vector only with a model that accepts such a length. For search, however, this tends to be bad: several topics merge into one representation and the returned document is too long. Excerpts that are too small, on the other hand, lose context.
- Split by structure. Headings, paragraphs, lists and sections often give better boundaries than a fixed number of characters.
- Preserve identity. Add the document title, parent heading, URL and version to the chunk.
- Use overlap sparingly. It can protect sentences at the boundary, but it creates duplicates and increases costs.
- Filter metadata before searching when it is a security condition. A user must not get someone else’s document just because it is semantically similar.
The RAG variants from simple search to GraphRAG and agentic control are compared in the article Types of RAG: from basic retrieval to GraphRAG and AI agents.
Where embeddings are used
- Semantic search: finds content by meaning, not just by word match.
- Recommender systems: connect users with similar products, films, music or courses.
- Clustering: reveals topics in customer queries, reviews or documents without hand-prepared categories.
- Classification: the embedding serves as input for a simpler model, or a new text is assigned to the nearest known examples.
- Deduplication and paraphrase detection: reveals nearly identical content even when rephrased.
- Anomaly detection: unusually distant points can signal a new type of request or an error in the data.
- AI agents: embeddings help search memory, documentation and the tool catalogue. They don’t create agency itself, though; the article What is an AI agent and how does it work explains more.
Limitations and common mistakes
Technical details that are easy to overlook
- Respect the model’s maximum input length and monitor the actual token count.
- Use exactly the same preprocessing, model version and recommended input format for documents and queries.
- Store the model identifier, dimension, chunking version and a hash of the source text. Without them the index is hard to reproduce.
- After a document changes, regenerate all affected chunks and remove the old vectors. Otherwise the system will return outdated content.
- Don’t confuse similarity with the final ranking. Language, freshness, source authority and permissions can carry the same or greater weight.
How to tell that embedding search works
Five convincing demos are not enough. You need a test set of real queries and, for each of them, labelled relevant documents. Ideally it includes short and long queries, text without diacritics, exact identifiers, synonyms, vague questions and cases for which no correct document exists.
In production, add anonymised feedback and regularly sample failed queries. The distribution of queries changes and an index that worked at launch may lag behind after months.
Frequently asked questions about embeddings
Key takeaways
- An embedding converts text, an image or another object into a fixed-length vector.
- Closeness of vectors expresses similarity learned by a specific model.
- Vectors can be compared by cosine similarity, dot product or distance according to the model’s recommendation.
- Embeddings power semantic search, recommendation, classification, clustering and retrieval in RAG.
- System quality is determined not only by the model but also by chunking, metadata, hybrid search, reranking, permissions and evaluation.
- Similarity is not truth and an embedding is neither encryption nor a security boundary.
Want to plug embeddings into a real AI application?
In the AI Agent Developer course we connect language models with documents, tools and application logic. You will learn to design retrieval, RAG and agentic workflows so that they work not only in a demo but also in practice.
Sources and further reading
- Google Machine Learning Crash Course: Embeddings — introduction to dense representations and the embedding space
- Mikolov et al.: Efficient Estimation of Word Representations in Vector Space — the original word2vec paper
- Reimers and Gurevych: Sentence-BERT — sentence embeddings for efficient semantic similarity
- Malkov and Yashunin: HNSW — graph index for approximate nearest neighbour search
- Model card: paraphrase-multilingual-MiniLM-L12-v2 — the model used in the example
